At Intuit, my team built a data pipeline that processed TurboTax e-filing data. This data needed to be made available for dashboards, analytics, and other downstream use cases.
One of the biggest challenges was protecting Personally Identifiable Information (PII) such as Social Security Numbers (SSNs).
SSNs are highly sensitive and must be protected at every stage of the data pipeline. At the same time, analytics teams sometimes need to perform legitimate business operations such as identifying records associated with a particular customer or performing exact-match lookups.
So how do you protect sensitive data while still allowing controlled equality searches without exposing the plaintext?
In this article, I’ll explain the encryption concepts behind this problem, including:
- Probabilistic vs. deterministic encryption
- Equality searches on encrypted data
- Base keys and derived keys
- Key separation
- Local vs. remote cryptographic operations
- Tokenization
- The security trade-offs involved in making encrypted data searchable
Why Encrypt PII?
PII such as SSNs, email addresses, phone numbers, and financial information is highly sensitive.
If you store plaintext PII directly in a data lake or database, a storage-layer compromise could expose large amounts of sensitive information.
Encryption provides protection by transforming plaintext into ciphertext:
Plaintext
   │
   ▼
Encryption + Key
   │
   ▼
Ciphertext
SSN: 111-22-3333
Encrypted: 8f92a7c1...Without the appropriate cryptographic key, the ciphertext shouldn’t reveal the original value.
For a data platform, though, encryption introduces another requirement.
Suppose an analytics application needs to find records for:
SSN = 111-22-3333If the SSN is encrypted, we don’t want the application to decrypt the entire dataset just to perform an equality lookup.
This is where deterministic encryption becomes useful.
AES: Advanced Encryption Standard
Before looking at probabilistic and deterministic encryption, let’s briefly understand AES (Advanced Encryption Standard).
AES is a widely used symmetric encryption algorithm for protecting sensitive data. It uses a secret key to transform plaintext into ciphertext, and the same key is used to decrypt the ciphertext back into the original plaintext.
The diagram below illustrates this basic process: the plaintext is encrypted using AES and a secret key to produce ciphertext. The ciphertext can then be decrypted using the same secret key to recover the original plaintext.
In real-world systems, AES is used with different encryption modes and constructions depending on the security and application requirements. The way randomness, initialization vectors, or nonces are handled affects properties such as whether repeated encryption of the same plaintext produces the same or different ciphertext.
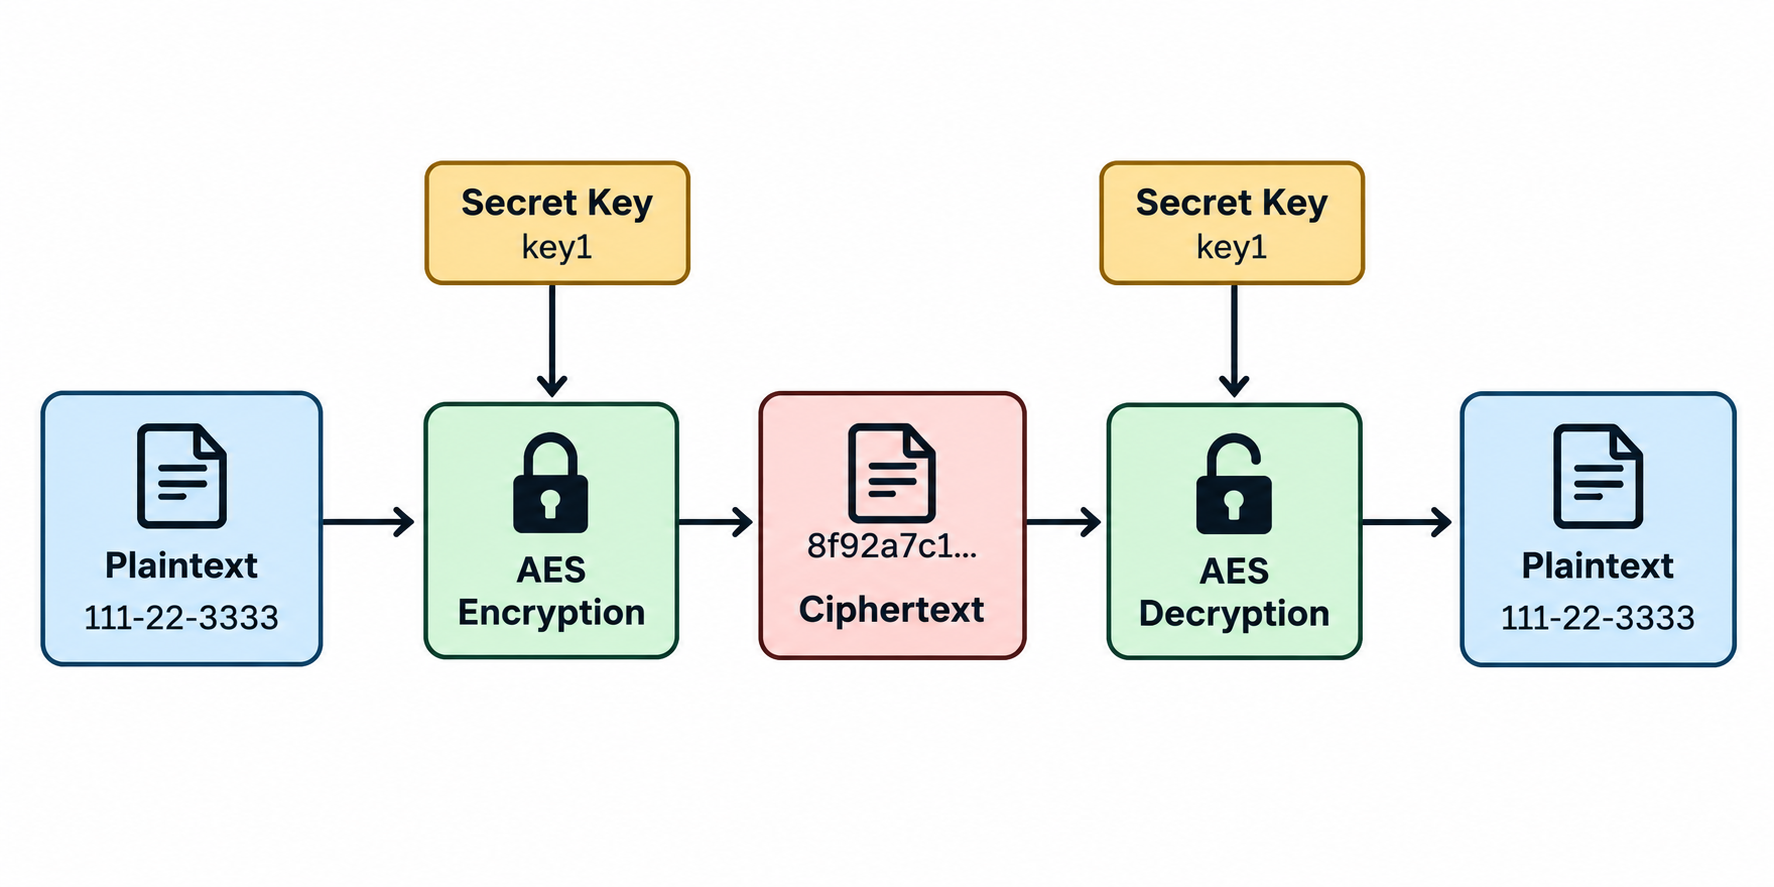
For example:
Plaintext:   111-22-3333
Key:         key1


        ↓ AES encryption


Ciphertext:  8f92a7c1...
AES is widely used to protect sensitive data such as PII. But how encryption behaves depends on how the encryption is constructed and used. One important distinction is whether randomness is used during encryption.
This brings us to probabilistic encryption.
Probabilistic Encryption
Probabilistic encryption introduces randomness during encryption.
This means that even when we encrypt the same plaintext with the same key, the resulting ciphertext can differ each time.
Encrypt("ABC", key1) → qwoeoewowe
Encrypt("ABC", key1) → cXcslslsd
Encrypt("ABC", key1) → fjkdfdfd
Although the input is the same — ABC — the encrypted values are different.
This randomness is intentional. It prevents someone looking at encrypted data from easily determining that two ciphertexts represent the same underlying value.
For example:
Record 1 → qwoeoewowe
Record 2 → cXcslslsd
Record 3 → fjkdfdfd
An observer can’t simply compare the ciphertexts and conclude that the records contain the same plaintext.
This makes probabilistic encryption a strong choice when confidentiality is the primary requirement.
Advantages
- Provides strong protection against equality-pattern analysis
- Makes repeated plaintext values look different after encryption
- Suitable when encrypted values don’t need to be directly compared
Limitation
The randomness that improves security also creates a challenge for analytics.
Suppose we want to find all records containing:
SSN = 111-22-3333If the same SSN was encrypted multiple times, we could have:
111-22-3333 → X8a91...
111-22-3333 → P72k4...
111-22-3333 → M91q2...
The encrypted values are different, even though the underlying SSN is the same.
Therefore, a simple equality query such as:
WHERE encrypted_ssn = encrypted_search_valuewouldn’t work reliably.
This creates an important trade-off for data platforms: randomness provides stronger protection against pattern leakage, but it makes equality-based searching more difficult.
When analytics requires exact-match searches on sensitive fields, we need a different approach: deterministic encryption.
Deterministic Encryption
Deterministic encryption is designed so that the same plaintext, encrypted under the same key and encryption context, produces the same ciphertext.
For example:
Encrypt("ABC", key)
    → adsfffdfd

Encrypt("ABC", key)
    → adsfffdfd

Encrypt("ABC", key)
    → adsfffdfd
The important property is:
Same plaintext
      ↓
Same key + context
      ↓
Same ciphertext
This allows equality matching:
SELECT *
FROM customer_data
WHERE encrypted_ssn = EncryptDeterministically(
    '111-22-3333',
    encryption_key
);
The application can generate the same ciphertext for the search value and compare it against the stored ciphertext.
The Security Trade-off
Deterministic encryption provides searchability, but that searchability comes at a cost.
Consider this dataset:
Ciphertext
-----------
A9F82...
A9F82...
B72AC...
A9F82...
C81DE...
An attacker may not know that:
A9F82... = 111-22-3333But they can determine that the same plaintext occurs three times.
In other words, deterministic encryption leaks equality patterns.
If an attacker has additional information about the underlying dataset, they may be able to use those patterns to infer plaintext values.
This is particularly important for fields with a small number of possible values, such as:
- State codes
- Boolean values
- Gender categories
- Small categorical fields
- Other low-entropy attributes
You should use deterministic encryption deliberately and only when the equality-search requirement justifies the additional leakage.
Base Keys and Derived Keys
Another important part of a secure encryption architecture is key management.
A common design uses a highly protected root or master key and derives separate keys for specific purposes, rather than using one key everywhere.
The diagram below illustrates key separation. Instead of using the same key for every type of data, a highly protected master key can serve as the root of a key hierarchy. Separate keys can then be created for different datasets, cryptographic purposes, or environments.
For example, a dataset key could be used for a particular data domain, while a purpose-specific key could be dedicated to encrypting SSNs. This limits each key’s scope and reduces the impact if one key is compromised.
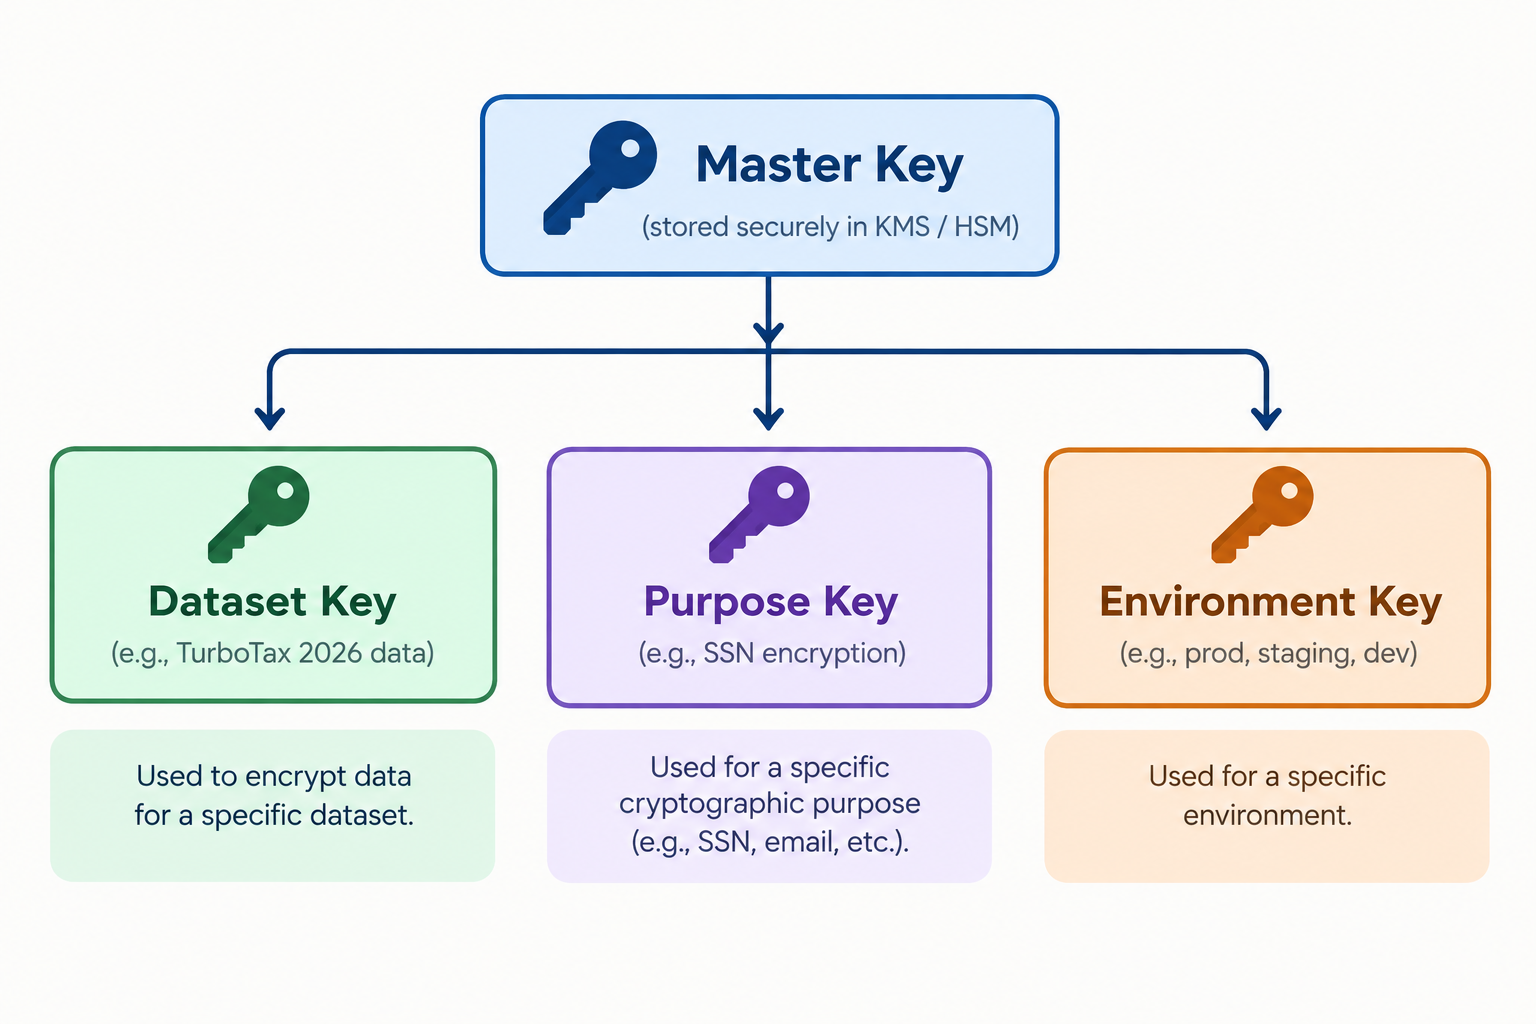
The idea with key separation is that different cryptographic purposes should use different keys or cryptographic contexts.
An organization might derive a key for:
Production + PII + SSN encryptionand another for:
Production + PII + Email encryptionThe exact hierarchy depends on the application’s security requirements.
Key Derivation with HKDF
A common standard for deriving cryptographic keys is HKDF, or HMAC-based Key Derivation Function.
HKDF (HMAC-based Key Derivation Function): A standard method to derive multiple keys from a single master key.
HKDF takes a master key and a context string — such as a dataset name, field name, or environment — and produces a derived key that is cryptographically independent from keys derived with different context strings. This means that compromising a derived key for SSN encryption does not compromise the derived key for email encryption, even though both originate from the same master key.
Where Does the Master Key Live?
The master key should never be stored in application code or configuration files. Instead, it should be stored in a dedicated secrets management system such as:
- A Key Management Service (KMS) such as AWS KMS, Google Cloud KMS, or Azure Key Vault
- A Hardware Security Module (HSM)
These systems provide access controls, audit logging, and hardware-backed protection for cryptographic keys.
Local Cryptographic Operations
In a local cryptographic operation, the application retrieves the key material from the KMS and performs encryption or decryption locally, within the application process.
Application → Request key → KMS
Application ← Return key ← KMS

Application performs encryption/decryption locally using the key
Advantages
- Low latency: encryption and decryption happen in-process without a network call per record
- Suitable for high-throughput data pipelines
Considerations
- The key material is present in application memory
- The application environment must be appropriately secured
- Key rotation requires updating the locally cached key
Remote Cryptographic Operations
In a remote cryptographic operation, the application sends the plaintext (or ciphertext) to the KMS, which performs the cryptographic operation and returns the result.
Application → Send plaintext → KMS
Application ← Return ciphertext ← KMS
The key material never leaves the KMS.
Advantages
- The key is never exposed to the application environment
- Centralized audit logging of all cryptographic operations
- Stronger key protection guarantees
Considerations
- Higher latency: each encryption or decryption requires a network call
- Potentially higher cost at scale, depending on KMS pricing
- The KMS must be highly available
For large data pipelines processing millions of records, the latency and cost of remote operations per record can be significant. A common pattern is to use the KMS to protect a data encryption key, and then use that data encryption key locally for bulk encryption — a pattern sometimes called envelope encryption.
Deterministic Encryption vs HMAC
An alternative to deterministic encryption for enabling equality searches is using an HMAC (Hash-based Message Authentication Code).
Instead of storing an encrypted value that can be decrypted, you store a keyed hash of the plaintext:
HMAC(key, "111-22-3333") → a93f2c...To search, you compute the HMAC of the search value and compare it against stored HMAC values:
SELECT *
FROM customer_data
WHERE ssn_hmac = HMAC(search_key, '111-22-3333');
Advantages of HMAC
- The stored value cannot be decrypted — it is a one-way transformation
- Equality searches are still possible
- Provides stronger protection than deterministic encryption in some threat models
Considerations
- The original plaintext cannot be recovered from the HMAC value alone
- If you need to decrypt the value later, you must store the encrypted ciphertext separately alongside the HMAC
- The HMAC key must be protected with the same care as an encryption key
HMAC is a useful approach when the goal is searchability without any need to recover the original plaintext from the stored token.
Tokenization
Tokenization is a different approach to protecting sensitive data. Instead of encrypting the plaintext in place, tokenization replaces the sensitive value with a randomly generated token that has no mathematical relationship to the original value.
111-22-3333 → tok_8f92a7c1A secure token vault stores the mapping between the token and the original value:
Token           Original Value
tok_8f92a7c1    111-22-3333
To retrieve the original value, an authorized system queries the token vault with the token. To search by SSN, the authorized system looks up the token for that SSN and then searches using the token.
Advantages
- The token itself reveals nothing about the original value
- The sensitive data is centralized in the token vault, which can be heavily access-controlled and audited
- Reduces the attack surface across downstream systems that only need to work with tokens
Considerations
- Requires a highly available and secure token vault
- The token vault becomes a critical dependency and a high-value target
- Lookup latency for every tokenization or detokenization operation
- Storage and operational overhead for the vault
Tokenization is widely used in payment card processing (PCI DSS compliance) and is increasingly used for other sensitive data domains.
Comparing the Approaches
| Approach | Searchable | Reversible | Key Leakage Risk | Pattern Leakage |
|---|---|---|---|---|
| Probabilistic encryption | No | Yes | Medium | Low |
| Deterministic encryption | Yes | Yes | Medium | Medium |
| HMAC | Yes | No* | Medium | Medium |
| Tokenization | Yes (via vault) | Yes (via vault) | Low | Low |
*Original value can be recovered if a separate encrypted copy is also stored.
Each approach involves trade-offs between searchability, recoverability, performance, and security. The right choice depends on your specific use case, threat model, and operational requirements.
Access Control Still Matters
Encryption and tokenization reduce the risk of data exposure, but they are not substitutes for strong access control.
Even with encrypted or tokenized data, you should apply:
- Column-level or field-level access control to restrict which systems and users can access sensitive fields
- Role-based access control (RBAC) to limit who can request decryption or detokenization
- Audit logging of all access to sensitive data and all cryptographic operations
- Data minimization: only expose sensitive fields to systems and users that genuinely need them
Encryption protects data at rest and reduces the blast radius of a storage-layer compromise. Access control limits who can interact with sensitive data in the first place. Both layers are necessary.
What We Learned from the Data Pipeline
Building a data pipeline for TurboTax e-filing data surfaced several practical lessons:
Identify your searchability requirements early. Not all PII fields need to be searchable. For fields that only need to be stored and retrieved by record ID, probabilistic encryption is the stronger choice. Deterministic encryption or HMAC should be used only for fields where equality searches are a genuine requirement.
Key management is as important as encryption. A well-designed encryption scheme with poor key management provides weak protection. Use a dedicated KMS, apply key separation, and rotate keys according to your organization’s key management policy.
Consider throughput and latency. For high-throughput pipelines processing millions of records, the cost and latency of remote KMS operations per record can be prohibitive. Envelope encryption — using the KMS to protect a data encryption key that is then used locally — is a common and practical solution.
Tokenization is worth considering for the most sensitive fields. For fields like SSNs, where the sensitivity is extremely high and downstream systems rarely need the plaintext, tokenization can provide stronger protection by centralizing the sensitive data in a heavily controlled vault.
Audit everything. Knowing who accessed what data and when is essential for compliance, incident response, and ongoing security monitoring.
Key Takeaways
- Probabilistic encryption provides strong confidentiality but does not support equality searches.
- Deterministic encryption enables equality searches but leaks equality patterns — use it deliberately and only when necessary.
- HKDF provides a standard way to derive purpose-specific keys from a master key, supporting key separation.
- Local cryptographic operations are suitable for high-throughput pipelines; remote operations via a KMS provide stronger key protection guarantees.
- HMAC can enable searchability without storing a decryptable ciphertext, useful when plaintext recovery from the stored value is not required.
- Tokenization replaces sensitive values with opaque tokens and centralizes sensitive data in a controlled vault, reducing the attack surface across downstream systems.
- Access control and audit logging are essential complements to encryption — cryptographic protection alone is not sufficient.
The right combination of these techniques depends on your specific use case, threat model, and operational constraints. Understanding the trade-offs allows you to make deliberate, well-reasoned decisions when designing data pipelines that handle sensitive PII.